
3.6×conversion rate
0.59% → 2.7% · CVR

If your current program runs a couple of opinion-led tests a quarter and revenue isn't moving, more ideas won't fix it. A better system will. We take over without throwing away what you've already learned.
For online shops from €100k a month. A free 30-minute call with the team.












Sound familiar?
You don't need convincing that CRO matters. You already pay for it. The calls are friendly, the slides look good, and a test or two goes live every month.
But nobody can tell you why those tests, in that order, or what they made in revenue. That's rarely a talent problem. It's the way the program is run.
A good switch isn't a restart. We keep what's worth keeping, drop the guesses, and run everything as Prediction-Based Experimentation: every idea gets its odds before it gets built.
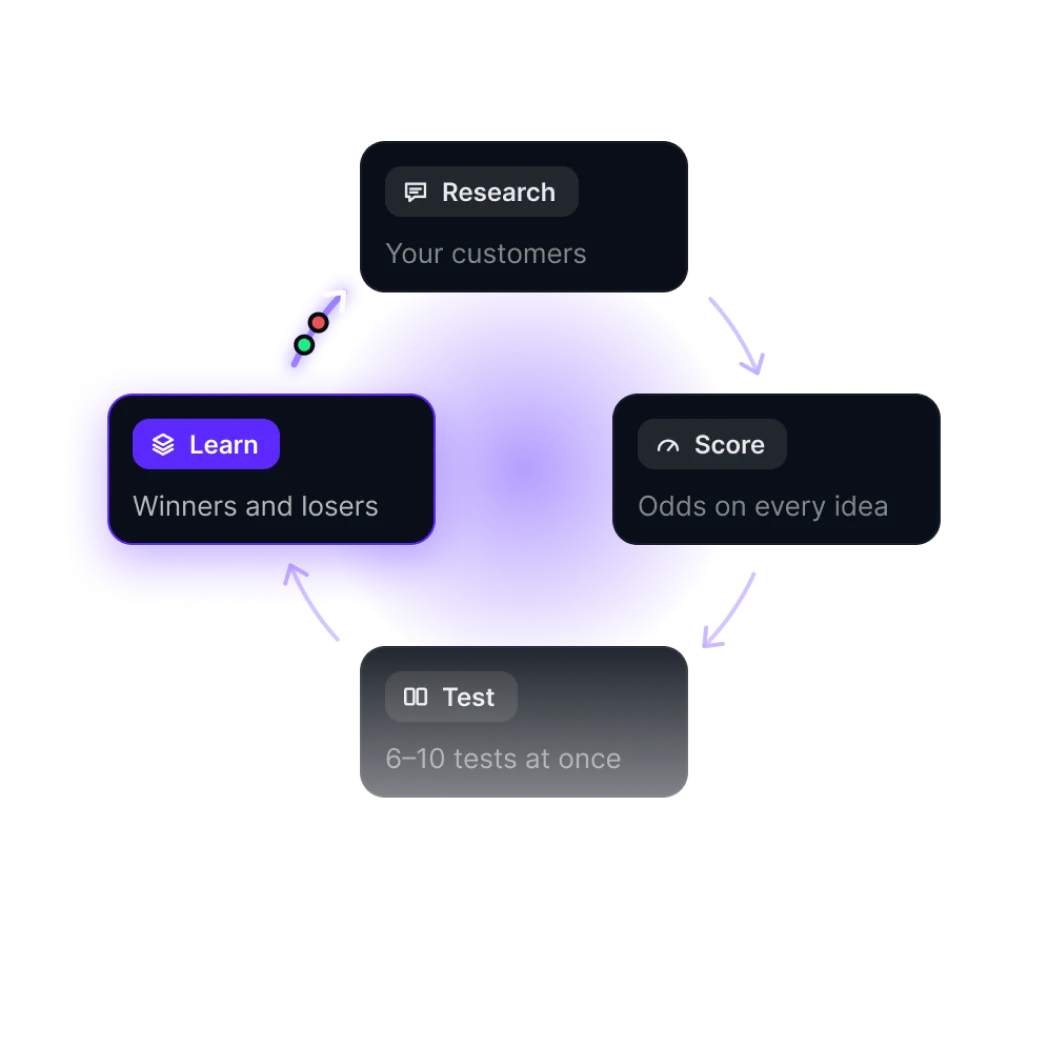
We start with your test archive, tracking, backlog and reporting, to separate real learnings from noise. Then comes the research your program was missing: reviews, surveys, support tickets, competitor reviews and 40+ hours of session recordings and heatmaps, turned into a 20+ page report on why your visitors buy.
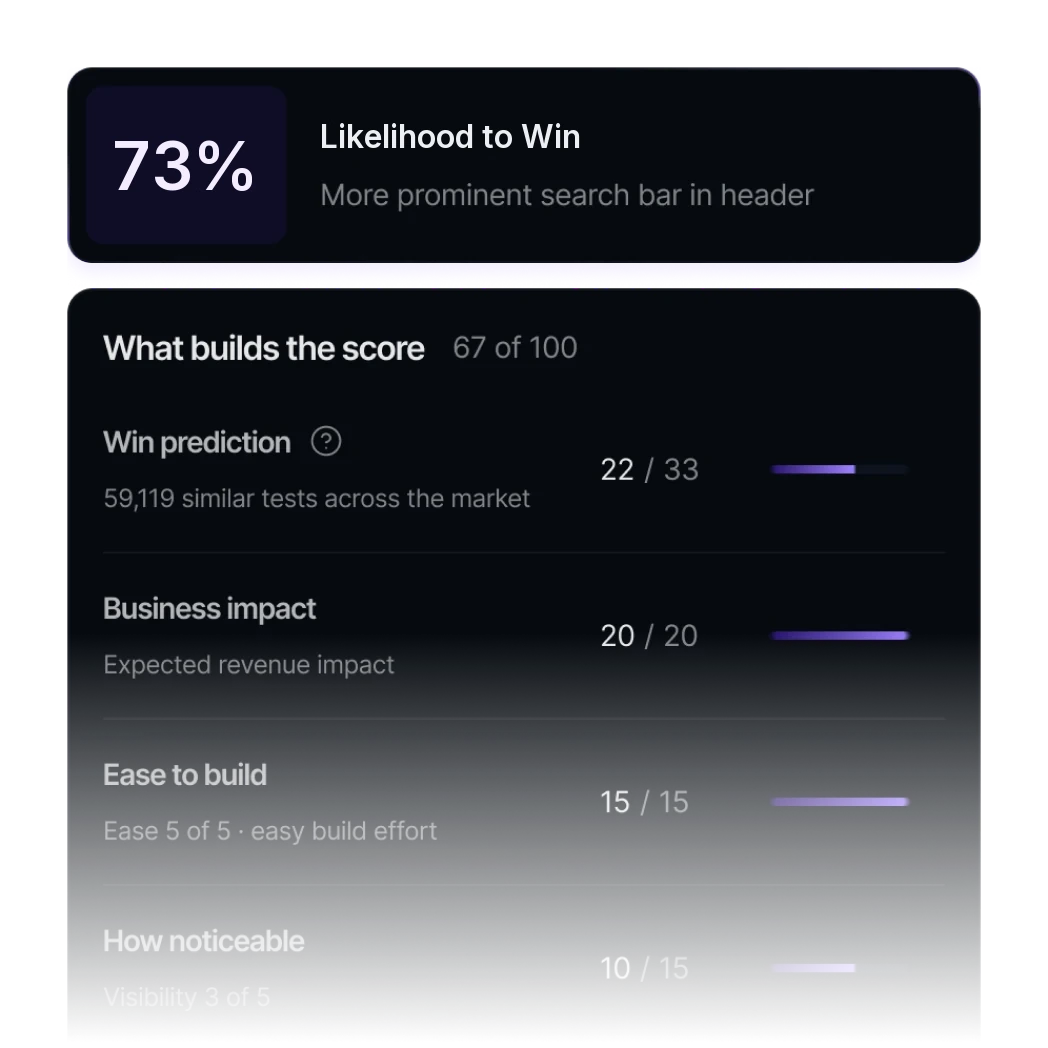
Your existing backlog and the new ideas all go through Apex, our own testing tool. Each gets a Likelihood to Win, based on the 4.3 million tests in our database, the 4,000+ we ran ourselves and the research on your shop. Scored on revenue exposure, Likelihood to Win and effort, the weak ones die on the list.
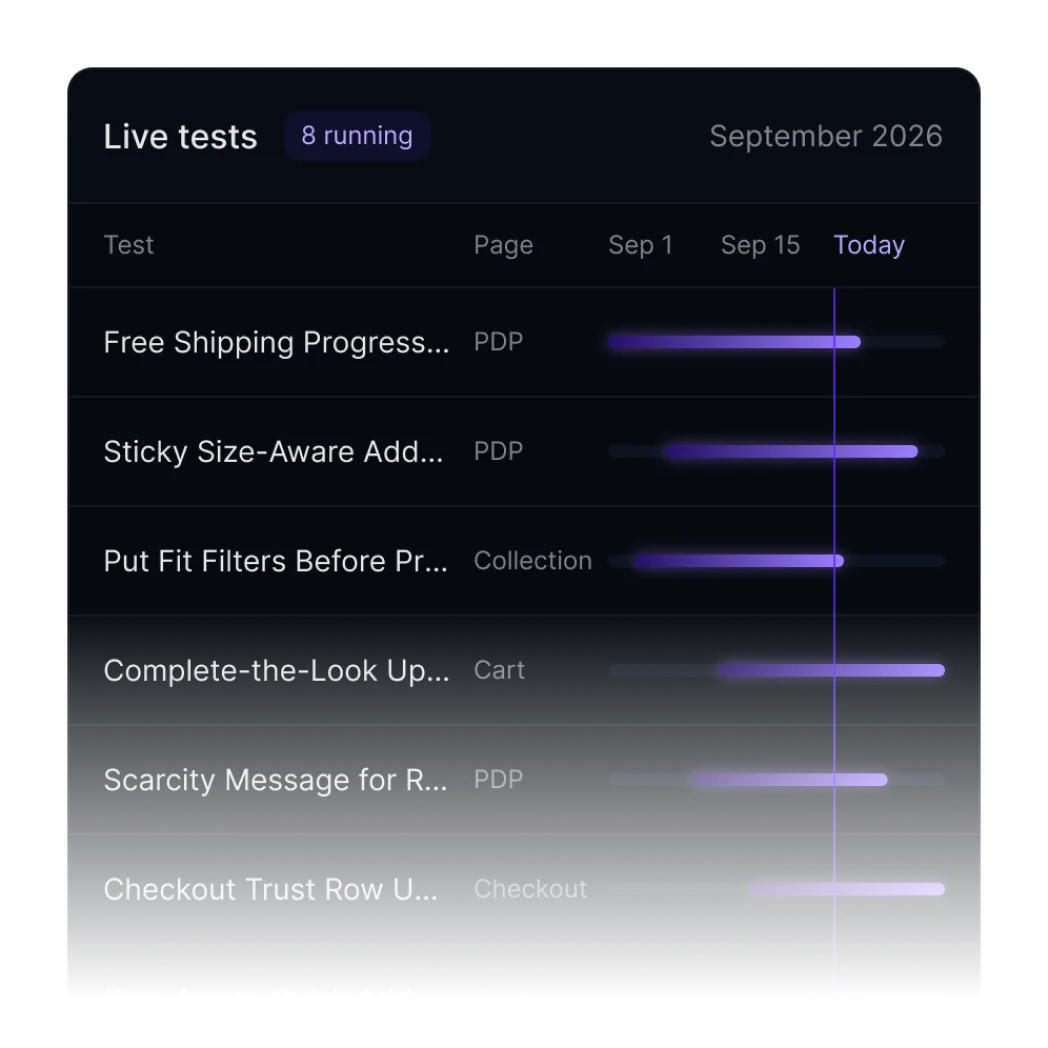
We build every variant at code level, no visual editors, and our QA team checks it on real devices, tracking included. Then six to ten tests run in parallel, each visitor assigned to each test independently. Microsoft found interference changes a decision in roughly one in 50,000 cases.
We measure revenue per visitor and fix the statistics before launch: frequentist, 80% confidence, 80% power, no early stopping. Every result gets filed by buyer motivation and friction point, documented, and it belongs to you, even if you leave us one day.
That's the short version. The full method, phase by phase, is on the process page.
See the full processTwo brands that needed more from testing than their setup was giving them.
0.59% → 2.7% · CVR
69% · Win rate
Everything your current program should have had, run by one team.

20+ pages on what drives your buyers and where your funnel leaks revenue, so ideas stop coming from best-practice lists.

Old and new ideas with their Likelihood to Win, revenue exposure and effort, re-ranked every two weeks on your results.

3 to 5 designed variants per test for mobile and desktop, your approval, and a code-level build.

Our 10-person QA team checks every variant on real devices via BrowserStack, tracking included, before it touches your traffic.

Clean 50/50 splits, sample-ratio checks and pre-registered statistics on every test.

Research memory, experiment pipeline and an executive view in revenue, plus a call with the team every two weeks.
When your current program can't explain why tests are prioritised the way they are, can't run enough experiments to learn anything, or can't connect its wins to revenue. If three or more of the points above sound familiar, a switch is worth a conversation.
Yes. We first look at each running test: its tracking, how it was built, its QA status and its decision rule. Tests with clean data run to the end, so you don't lose what they'll tell you. Tests with unreliable data or a risky build get stopped.
No. We read your archive, winners, losers and unclear results, and carry the learnings worth keeping into the new backlog. The point isn't to throw away past work. It's to separate what's real from weak tests and broken tracking. And everything you learn with us is documented and belongs to you.
In the first month, the research is done, the plan is scored and the first tests are live. We ramp up until six to ten tests run in parallel. By month three, your shop has usually run more experiments than most brands ship in a year.
Your program runs on Apex by DRIP, the testing tool we built ourselves. It holds the research, the ranked backlog with a Likelihood to Win on every idea, the live tests and the dashboards. Apex is included in our service and only exists inside DRIP.
Yes. There are two ways to work with us. Full service, where our team does the work, is what most clients choose. Or consulting, where your team builds and launches the tests with Apex and a call with us every two weeks. Either way, your team keeps the context and the ownership.
Book a call with the team. We look at your test velocity, research, builds and reporting, and tell you where the program leaks revenue, whether or not you switch to us.
30 minutes, and you'll know exactly where your shop stands.
The guarantee, in full
When you can predict what wins, you can promise the outcome. What counts as uplift, how it's measured, and what happens if we miss is written down in plain language.
We can promise it because we know our numbers: more than 50% of our A/B tests win, across 4,000+ documented experiments. The guarantee stands when our team runs the program for you.