
3.6×conversion rate
0.59% → 2.7% · CVR

Most shops optimize from best-practice lists and gut feel. We start with why your visitors buy, put odds on every idea before it gets built, and run six to ten A/B tests at once. That's why more than 50% of our tests win.
For online shops from €100k a month. A free 30-minute call with the team.












Sound familiar?
You redesigned the site. Twice. You worked through the checklists and copied what your fastest-growing competitor does. Maybe an agency ran a few tests a quarter and called it optimization.
The conversion rate is still flat. Ads get more expensive every year, and the gap between what you pay for traffic and what it earns keeps growing. The problem isn't effort. It's the approach.
We call it Prediction-Based Experimentation: research first, odds on every idea, many tests at once, and every result feeding the next. Four steps, repeated every month.
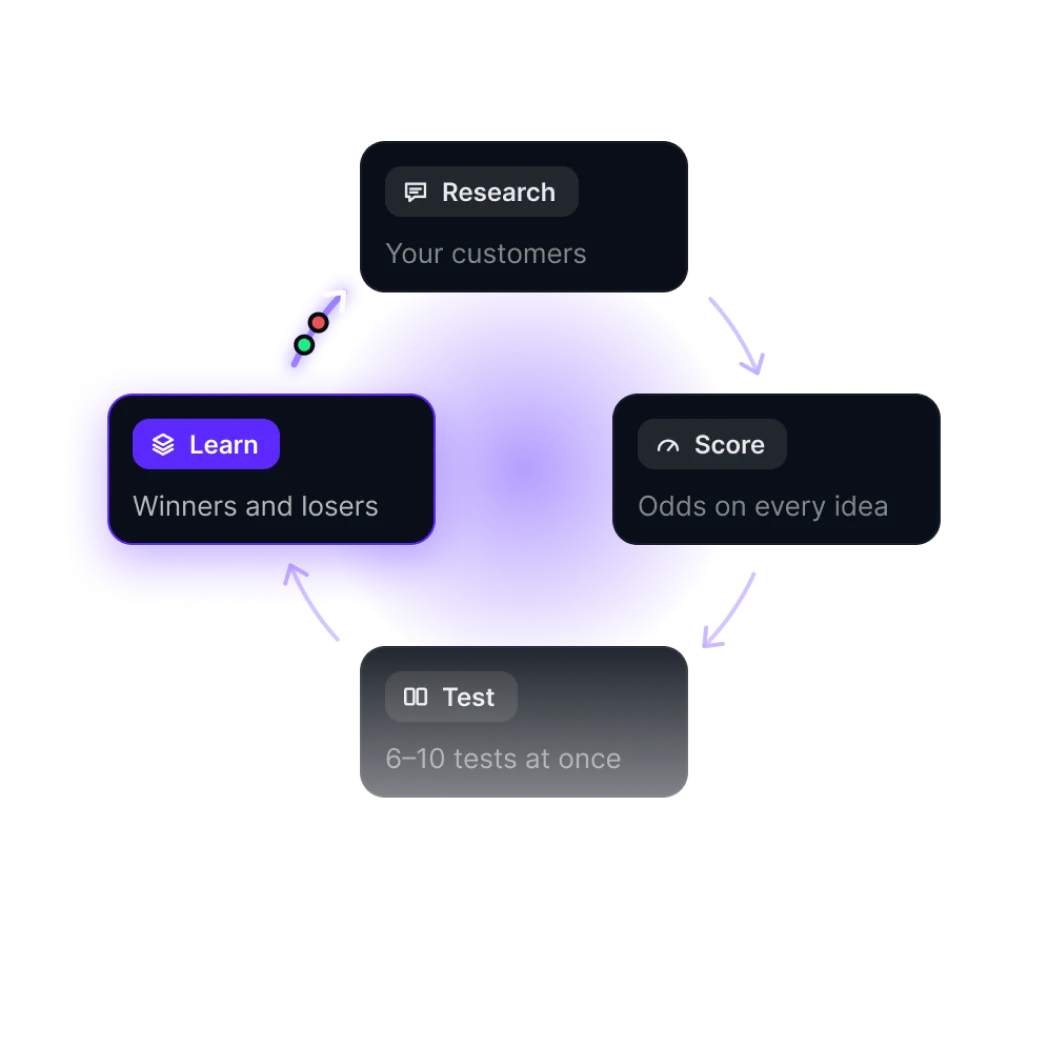
The first month is research. Reviews, surveys, support tickets, your competitors' reviews, ten analyses of your funnel and 40+ hours of session recordings and heatmaps. We look for where revenue leaks, and why. You get a 20+ page report, and every idea on your list is written as if, then, because.
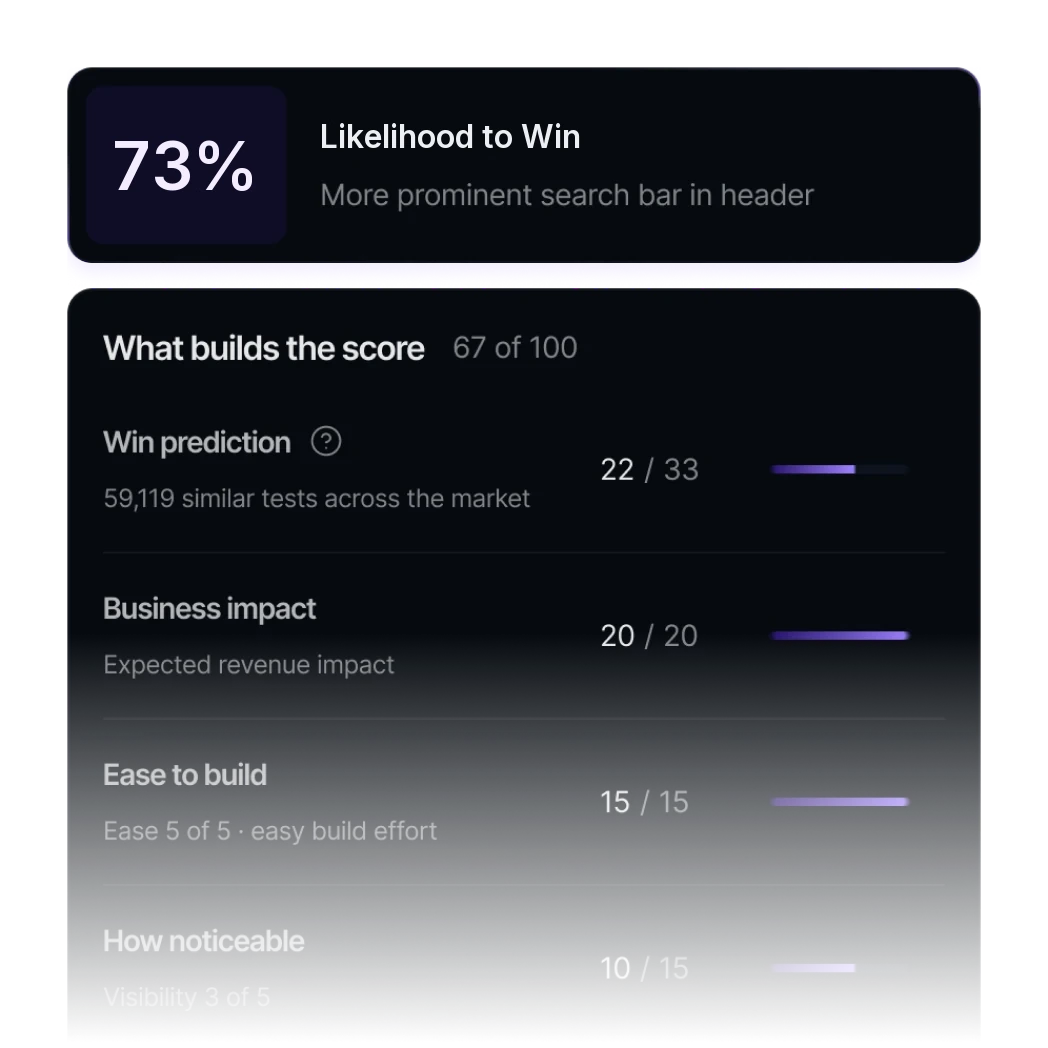
Apex by DRIP, our own testing tool, gives every idea a Likelihood to Win, based on one of the largest A/B test databases in e-commerce: 4.3 million tests from 151,000 shops. Together with revenue exposure and effort, that becomes a weighted impact score that decides what gets built first. It's recalibrated every two weeks on your results.
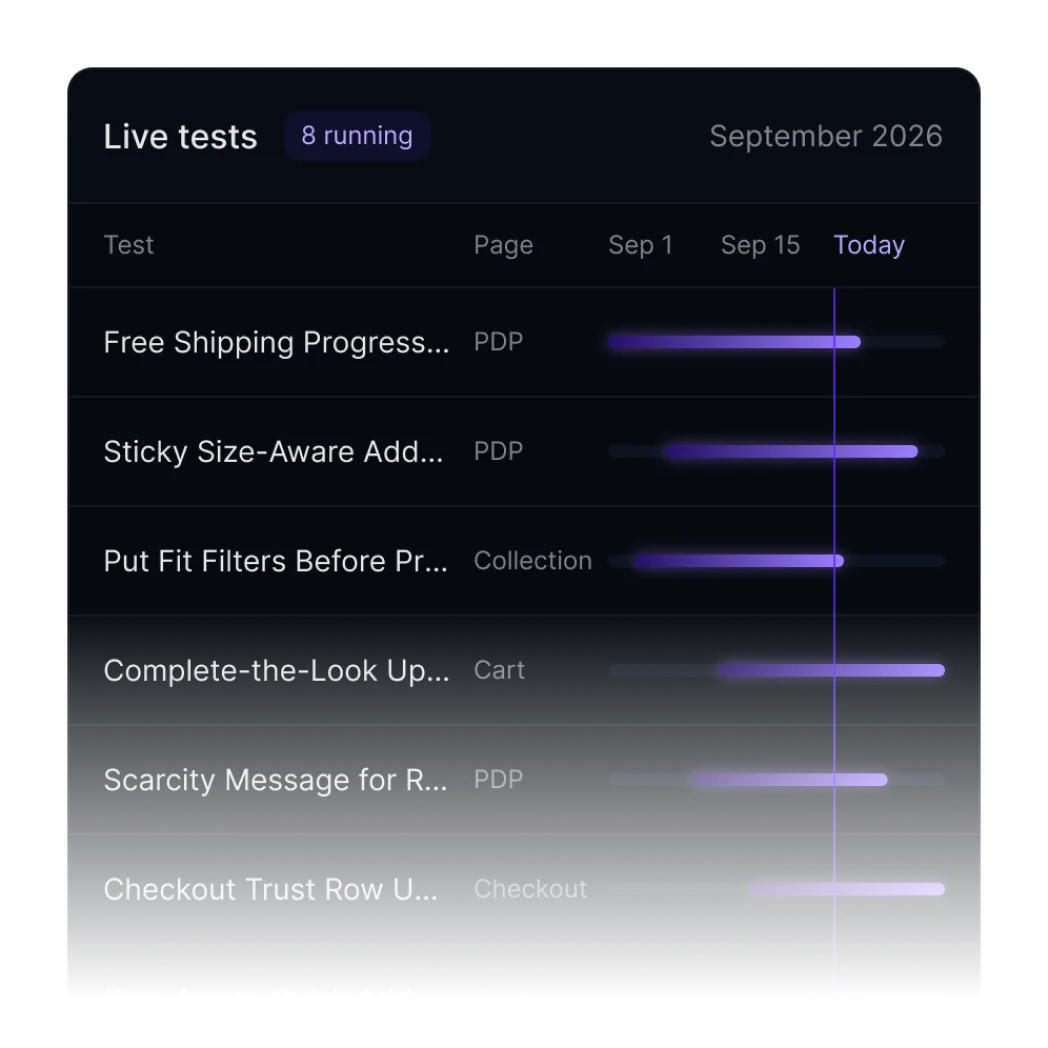
Every test gets a brief and 3 to 5 designed variants for mobile and desktop that you approve. We build in code, not in a visual editor, and our QA team checks each variant on real devices. Then six to ten tests run in parallel on clean 50/50 splits.
We measure revenue per visitor, with the statistics fixed before launch: 80% confidence, 80% power, no early stopping. Winners ship. Every result, including the 40 to 50% that come back negative or unclear, gets filed by buyer motivation and friction point, so the next round of ideas starts with better odds.
That's the short version. The full method, phase by phase, is on the process page.
See the full processTwo shops with very different problems, and the same method behind both.
0.59% → 2.7% · CVR
€3.2M · Generated
One team and one program, from the first research call to the shipped winner.

20+ pages on why your visitors buy, why they don't and where your funnel leaks revenue.

Every idea scored on revenue exposure, Likelihood to Win and effort, and re-ranked every two weeks.

3 to 5 variants per test for mobile and desktop, all before anyone writes code.

Every variant built in code and checked by our QA team on real devices, tracking included.

Clean 50/50 splits, sample-ratio checks and statistics fixed before launch.

Your research, your test pipeline and an executive view in revenue, plus regular time with the team.
Everything a conversion program needs, from one team of 70+ people: strategists, behavioural psychologists, data analysts, designers, developers and a QA team. That covers the research, the ranked backlog, test design and development, QA on real devices, the statistics, the reporting and a call every two weeks. Apex by DRIP, our own testing tool, is included, so there's no separate tool subscription.
To do this in-house you'd need at least a CRO manager, a designer, a developer, a QA engineer and a data analyst, plus the time it takes a new team to learn what works. With us you start on day one with a trained team, Apex and one of the largest A/B test databases in e-commerce. Everything we learn is documented and belongs to you, even if you leave.
We ramp up until six to ten tests run in parallel at any time. By month three, most shops have run more experiments than most brands ship in a year. The exact pace depends on your traffic and on how many pages carry enough revenue to test on.
We work with online shops, whatever they run on: Shopify, Shopify Plus, WooCommerce, Magento, headless and custom storefronts. Every test is built at code level rather than in a platform's visual editor. How your stack is set up is one of the first things we look at on the call.
Every visitor is assigned to every test independently, on a 50/50 split, and we monitor each test for sample-ratio mismatch. According to Microsoft's research, interference between parallel tests changes a decision in roughly one in 50,000 cases. That's why Booking.com runs over 1,000 tests at once.
In month one the research is done, the plan is scored and the first tests are live. A result counts once a test reaches the sample size fixed before launch, not earlier. Month six is when the guarantee comes due and the lift gets measured.
Yes. Our team works in English and German, and the method starts from your buyers, not from a market. Size matters more than location: we work with online shops from €100k a month in revenue.
A winning test keeps earning after it ships, without extra ad spend. Paid traffic stops paying the moment you stop paying for it. Across 250+ brands, our work has added €500M+ in revenue. That record is why we can offer the guarantee: at least 10% more revenue in under six months, or month seven onward is free.
Book a call with the team and tell us about your shop. We'll talk through where it stands, where revenue leaks and where we'd start. If CRO isn't the best use of your money right now, we'll tell you.
30 minutes, and you'll know exactly where your shop stands.
The guarantee, in full
When you can predict what wins, you can promise the outcome. What counts as uplift, how it's measured, and what happens if we miss is written down in plain language.
We can promise it because we know our numbers: more than 50% of our A/B tests win, across 4,000+ documented experiments. The guarantee stands when our team runs the program for you.