
€12.2Mover 3 years
25.3× · Program ROI

When testing spreads across brands, markets and teams, it usually spreads thin: different rules, different tools, nothing shared. We run one method across all of them, with fixed statistics, one memory for every result and reporting your leadership can actually read.
For online shops from €100k a month. A free 30-minute call with the team.












Sound familiar?
Your first shop ran A/B tests and it worked. The board noticed. Now leadership wants testing everywhere, every brand, every market. What worked with one team and one storefront falls apart at that scale.
Each team picks its own tool, its own rules, its own way to read a result. Six months later five teams are testing, none of the results compare, and nobody can tell leadership whether any of it makes money.
Prediction-Based Experimentation, with the same rules for every brand and every market. Four steps.
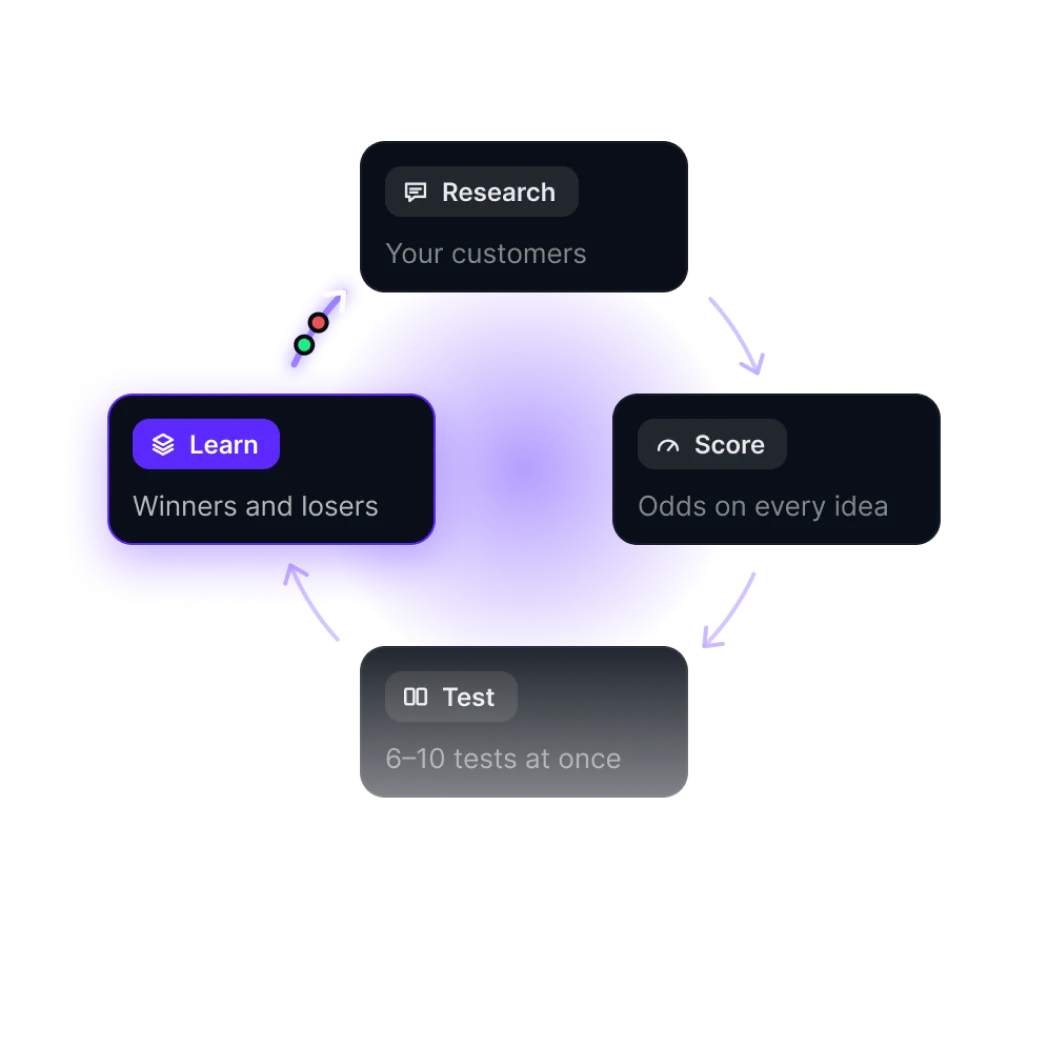
Every brand gets its own research month: reviews, surveys, support tickets, competitor reviews, ten analyses and 40+ hours of session recordings and heatmaps. Each ends in a 20+ page report on why that brand's buyers buy and where its funnel leaks revenue. Same method everywhere, so the findings compare across brands.
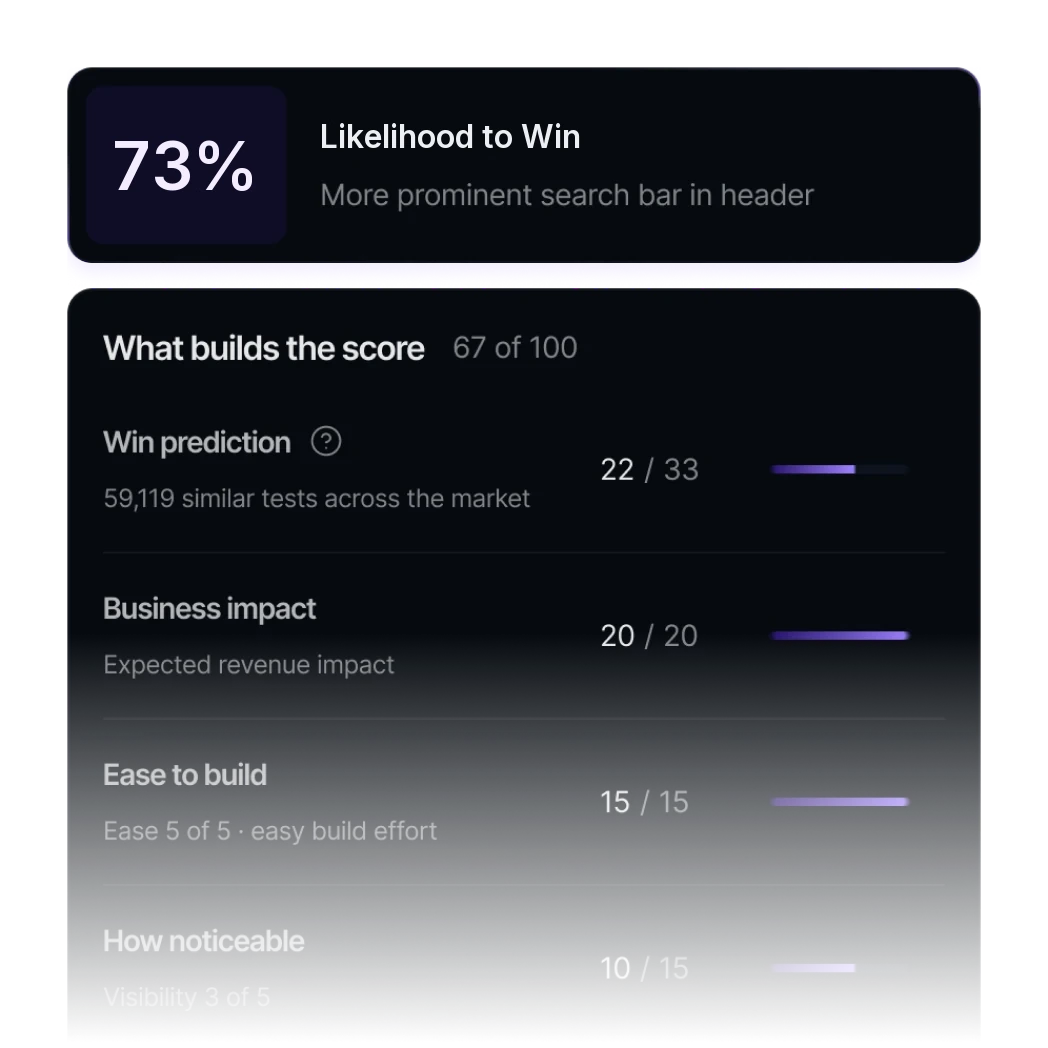
Every idea, from every team, gets scored the same way in Apex by DRIP, our own testing tool: revenue exposure, Likelihood to Win and effort. The likelihood draws on 4.3 million tests, the 4,000+ we ran ourselves and the research on that shop. Priorities stop being a negotiation between stakeholders, and the ranking recalibrates every two weeks on results.
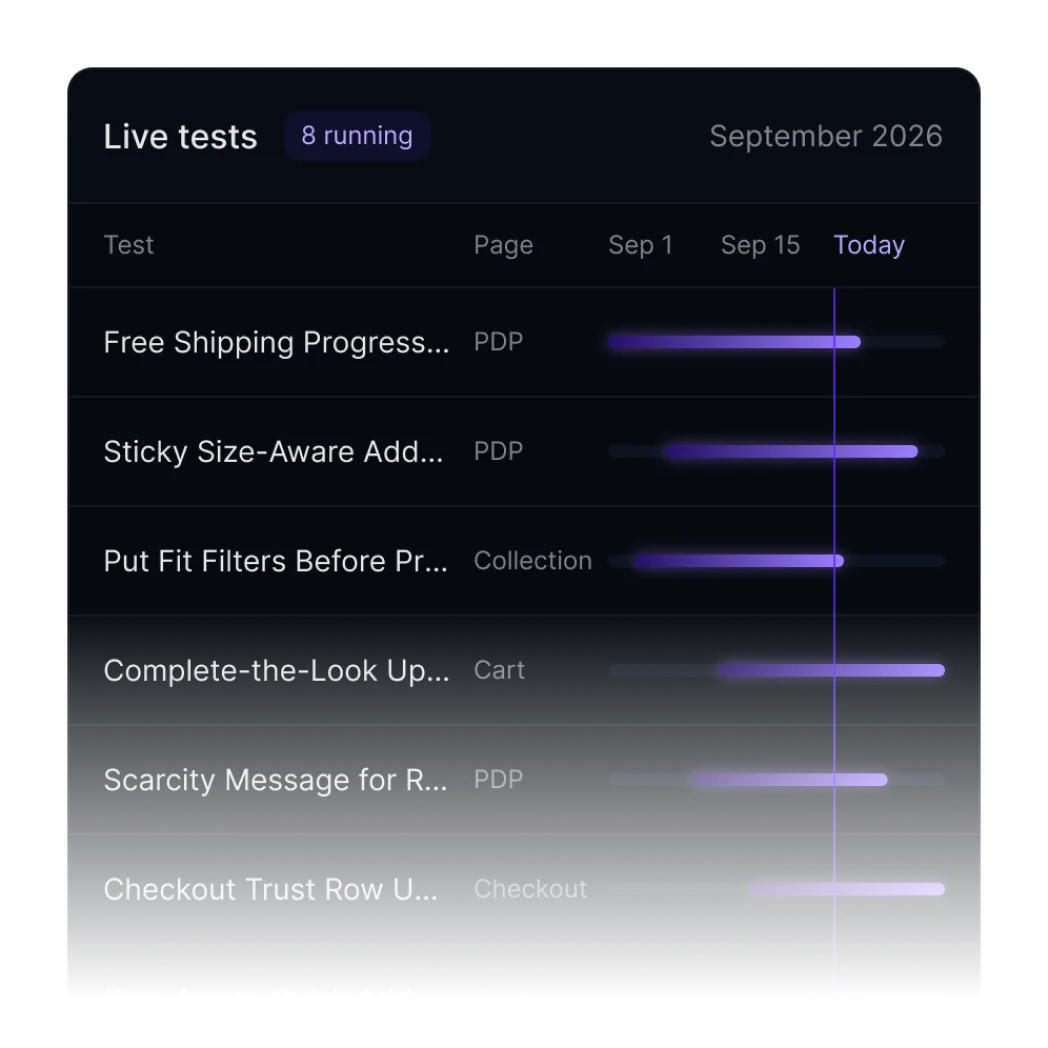
Briefs and 3 to 5 designed variants the brand team approves. Code-level builds and a 10-person QA team on real devices, tracking included. Then six to ten tests at once per shop, 50/50 splits, sample-ratio mismatch monitored, and statistics pre-registered to one standard: frequentist, 80% confidence, 80% power, no early stopping. A result from one brand means the same as a result from another.
Every result, win or lose, gets filed by the buyer motivation it confirmed and the friction it exposed, so a lesson from one brand can shape the next idea for another. Leadership gets an executive view in revenue per visitor, teams get the pipeline and the research memory. Everything learned is documented and belongs to you, even if you ever leave.
That's the short version. The full method, phase by phase, is on the process page.
See the full processOne steered a premium footwear brand out of a revenue drop. One ran alongside SNOCKS while it grew into its own online brand.
25.3× · Program ROI
350+ · A/B tests run
One method, one standard and one memory across every brand you bring in.

20+ pages per brand on what drives its buyers and where its funnel leaks revenue, built the same way so the findings compare.

Revenue exposure, Likelihood to Win and effort for every idea from every team, re-ranked every two weeks.

Pre-registered frequentist tests at 80% confidence and 80% power, effect size and duration fixed upfront, no early stopping.

Our 10-person QA team checks every variant on real devices via BrowserStack, tracking included.

The research memory, the experiment pipeline and an executive view with revenue per visitor, shipped winners and the next best bets.

Every result documented and filed by what it revealed, owned by you, with a call with the team every two weeks.
Separate programs mean separate methods, separate knowledge and separate reporting, so nothing learned at one brand reaches the others. An enterprise program puts one layer on top: one statistical standard, so results compare, one scoring model, so priorities are set the same way everywhere, and one memory, so a winner at one brand becomes an idea with better odds at the next. At Coop, one central program supports 10 e-commerce brands.
Frequentist, pre-registered before launch: 80% confidence, 80% power, minimum detectable effect and duration fixed upfront, no early stopping. At scale this matters more, because one brand's result shapes decisions across the portfolio, and a fake win spreads. Running many tests at once is not the risk people think: parallel-test interference changes a decision in roughly one in 50,000 cases (Microsoft checked), and Booking.com runs over 1,000 at once.
The research, the scoring and the statistics sit above the platform. Every test is built at code level, no visual editors, and checked by our QA team on real devices, so the workflow is the same whether one brand runs on Shopify Plus and another on a custom headless stack.
The first shop starts like any other: in month one the research is done, the plan is scored and the first tests are live. Further brands or markets come on one after another, each with its own research month, on the same rules. By month three, a shop in the program has usually run more experiments than most brands ship in a year.
In revenue per visitor, per test and per brand, rolled up in an executive view with shipped winners and the next best bets. We say upfront that 40 to 50% of tests come back negative or unclear, so ROI is read across the portfolio, not test by test. When our team runs the program, the guarantee applies: at least 10% more revenue in under six months, or month seven onward is free.
Yes. That's what consulting is for: your teams build and launch the tests with Apex, and we set the plan, hold the statistical standard and read the results with you in a call every two weeks. Or we run everything ourselves in full service, which is what most clients choose. Either way, everything learned is documented and stays with you.
Book a call and tell us how testing runs across your brands today. We'll talk through what one method and one memory would change, and tell you straight whether it's worth it for you.
30 minutes, and you'll know exactly where your shop stands.
The guarantee, in full
When you can predict what is likely to win, you can promise the outcome. What counts as uplift, how it's measured, and what happens if we miss is written down in plain language.
We can promise it because we know our numbers: more than 50% of our A/B tests win, across 4,000+ documented experiments. The guarantee stands when our team runs the program for you.