
€12.2Mover 3 years
25.3× · Program ROI

What wins in Germany can lose in France. We research your buyers market by market, put odds on every idea with a database of 4.3 million A/B tests, and run six to ten tests at once. Each market gets its own read, and every result sharpens the next idea everywhere.
For online shops from €100k a month. A free 30-minute call with the team.












Sound familiar?
You ran a test in Germany. It won, so it shipped everywhere. Three months later the UK is flat, France looks worse, and nobody can say whether that's the test or the season.
Or it goes the other way: every country team runs its own tests, with its own opinions, and nothing one market learns ever reaches another.
We call it Prediction-Based Experimentation: every idea gets its odds before it gets built. Four steps, repeated every month.
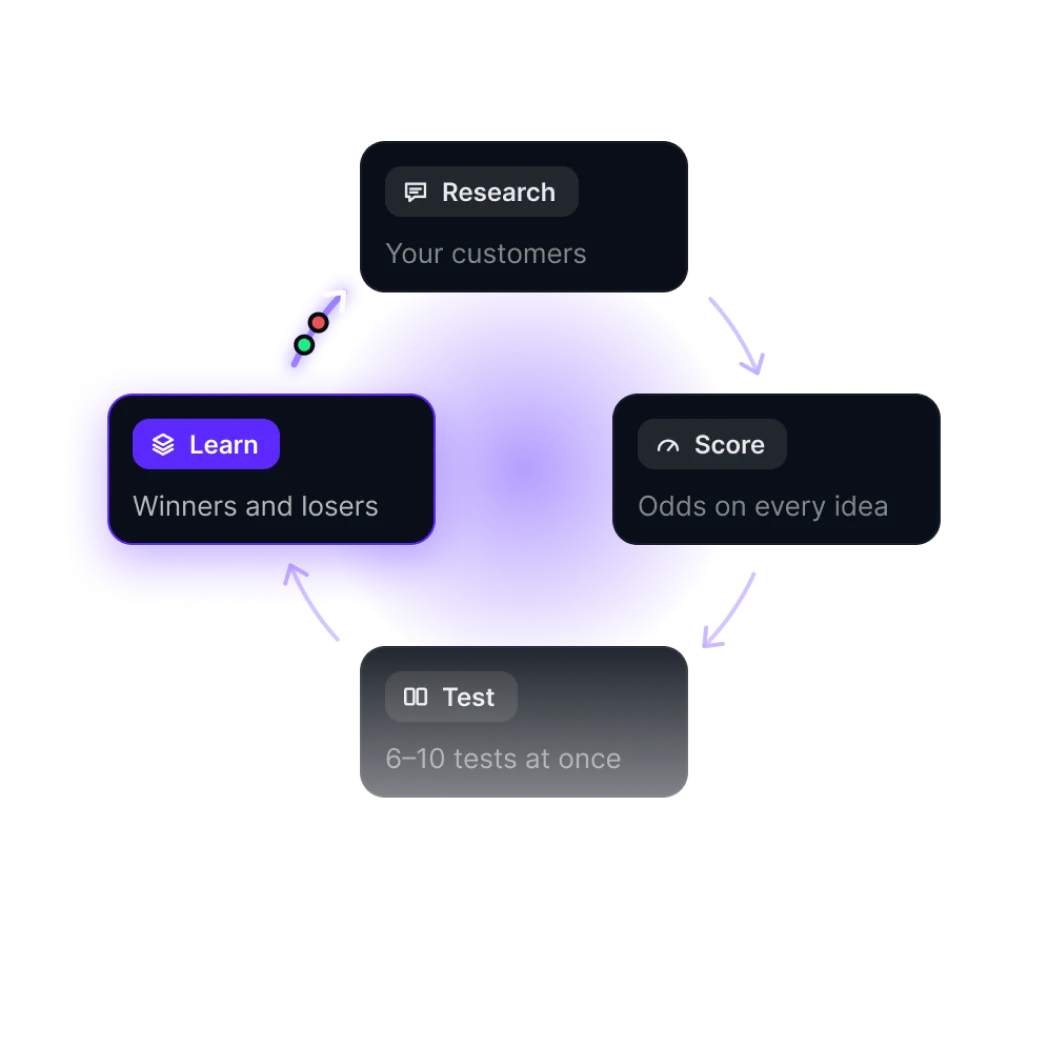
The first month is research. We read your reviews, surveys, support tickets and your competitors' reviews from the markets that carry your revenue, and put 40+ hours into session recordings and heatmaps. Our behavioural psychologists turn it into a 20+ page report on why your buyers buy, why they don't, and where the markets differ.
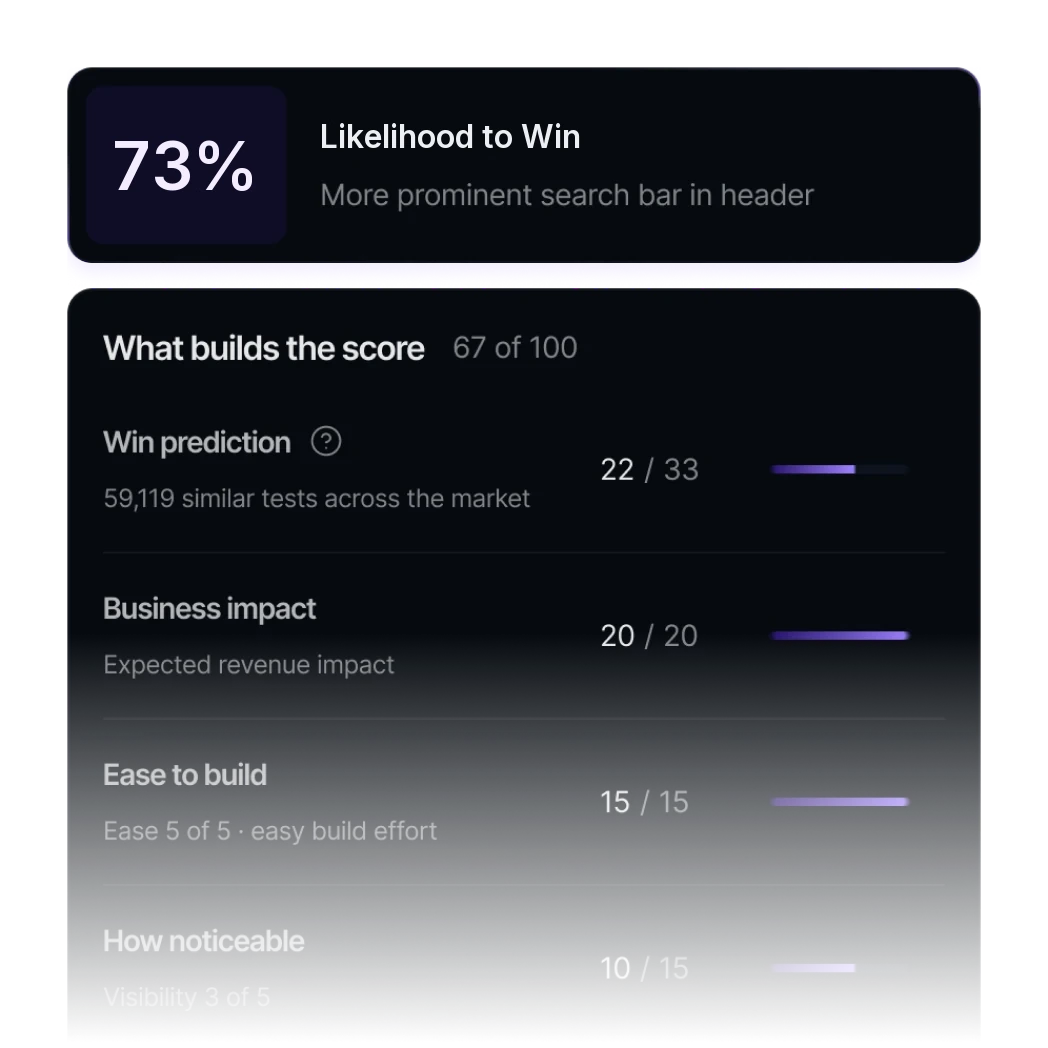
Before anything gets built, Apex, our own testing tool, gives every idea a Likelihood to Win, based on the 4.3 million tests in our database, the 4,000+ we ran ourselves and what the research says about your shop. Then we rank the ideas by revenue at stake, Likelihood to Win and effort, so the first tests go where the most money is.
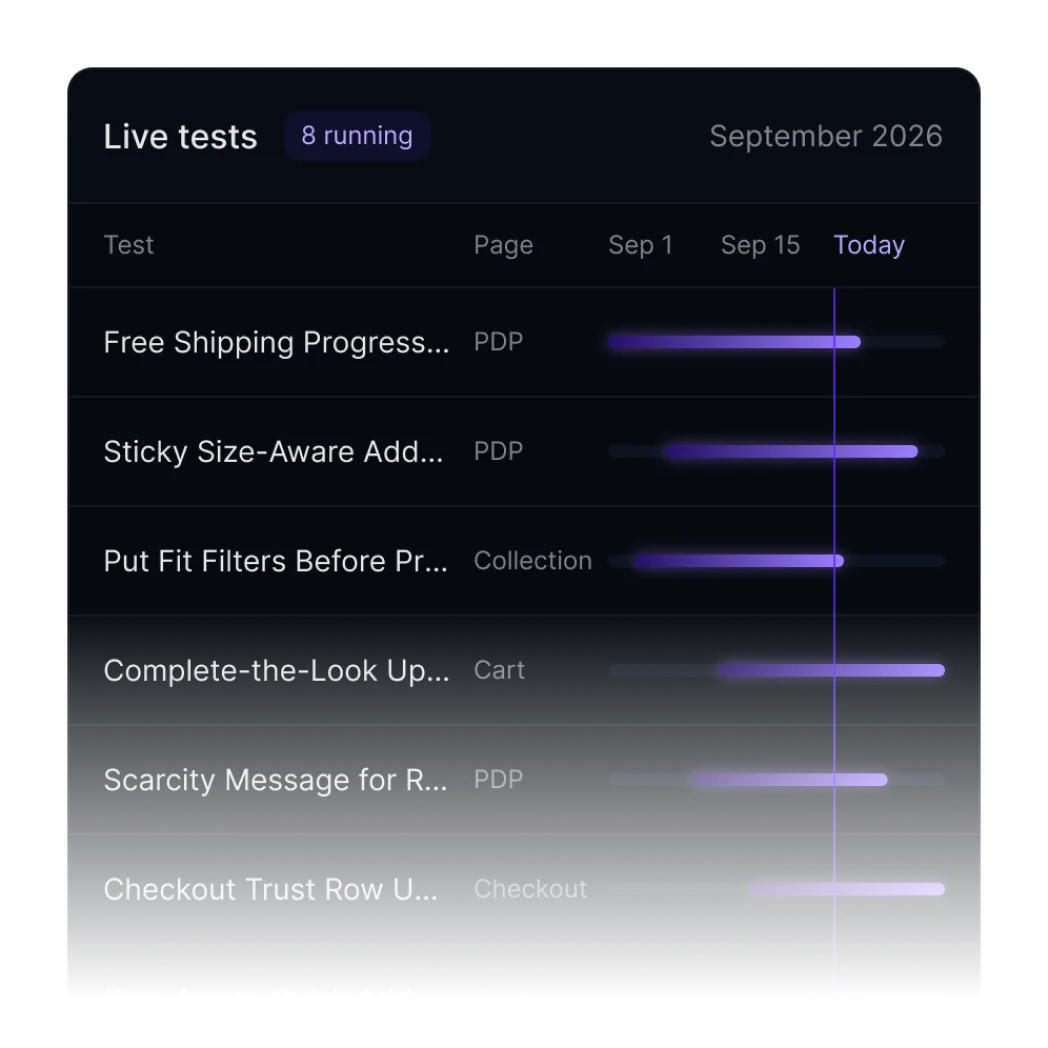
We design localised variants, build them at code level and QA them on real devices. Six to ten tests run in parallel, and each market gets its own read with its own sample size, fixed before launch: frequentist, 80% confidence, 80% power, no early stopping.
We measure revenue per visitor, not clicks. Every result, win or lose, gets filed by the buyer motivation and friction point it touched. When a pattern holds in one market, it becomes a new idea for the others, with its own odds, instead of a copy and paste.
That's the short version. The full method, phase by phase, is on the process page.
See the full processTwo brands selling across Europe, with a testing program that runs all year.
25.3× · Program ROI
18 · Winning tests
Everything a multi-market testing program needs, run by one team.

20+ pages on what drives your buyers in the markets that matter, where they differ and where each funnel leaks revenue.

Every idea with its Likelihood to Win, the revenue at stake and effort, re-ranked every two weeks on your results.

3 to 5 designed variants per test for mobile and desktop, approved by you, then a code-level build.

Our 10-person QA team checks every variant on real devices, tracking included, before it touches your traffic.

Clean 50/50 splits, sample-ratio checks and pre-registered statistics on every test, in every market.

Three dashboards, a call with the team every two weeks, and every result documented. It belongs to you, even if you leave.
We plan every test around your consent setup, check your analytics and data protection setup before the first launch, and document how visitors are assigned to variants and where the data goes. Tests run for the visitors your consent setup allows. Compliance depends on that setup as much as on the testing tool, so we check it with your data protection team rather than promise it on a website.
Yes. Each market runs as its own test, with its own control, sample size and duration fixed before launch. We don't pool the markets, because an average hides the signal: a win in Germany and a loss in France can add up to a small win that quietly costs you money in France. Smaller markets need longer to reach a result, and we tell you upfront how long.
Our deepest experience is in the German-speaking markets, where most of our clients are based. Many of them sell across Europe, and we test their other markets too, like Oceansapart's French shop. If your main markets are ones we know less well, we'll say so on the call.
A lot. Buyers in different markets trust different signals, prefer different payment methods and expect different return terms. So we don't assume a winner in one market wins in the next. The research shows what drives buyers in each market, and every idea gets its Likelihood to Win with that in mind.
Your program runs on Apex by DRIP, the testing tool we built ourselves. It's included in the service, so there's no separate tool subscription. Before the first test we check your consent and analytics setup and document how visitors are assigned and where the data flows.
Every result, win, loss or unclear, gets filed by the buyer motivation and friction point it touched. When a pattern holds in one market, it goes on the list for the others as a new idea with its own odds, and it gets tested there, not copied. When a test wins in one market and loses in another, that difference is a finding too, and it shapes the next idea. Everything is documented and stays yours.
Book a call with the team. Tell us where you sell and what you've tested so far, and we'll tell you where we'd start and whether we're the best use of your money.
30 minutes, and you'll know exactly where your shop stands.
The guarantee, in full
When you can predict what is likely to win, you can promise the outcome. What counts as uplift, how it's measured, and what happens if we miss is written down in plain language.
We can promise it because we know our numbers: more than 50% of our A/B tests win, across 4,000+ documented experiments. The guarantee stands when our team runs the program for you.